
Reliable answers
The assistant is at its sharpest in a short, focused conversation about one topic. The longer and fuller a chat becomes — many questions, many documents, several topics mixed together — the more the assistant has to hold in view at once. At some point it can start to mix up details or “fill in” a passage that isn’t literally there. This isn’t a Prudai quirk: it applies to every current AI model and it’s measurable — the longer the conversation, the higher the chance of such mistakes.
The good news: this is largely in your own hands.
Start a new chat per topic
Section titled “Start a new chat per topic”This is by far the most effective habit. Begin a new chat for each new topic or part of the case file. A short, focused chat keeps the assistant anchored to exactly the documents that matter for that question — and that is precisely what stops it from mixing up sources.
Rules of thumb:
- New topic? New chat. Don’t carry one chat from the liability question to legal costs to the writ of summons.
- Keep the number of documents per chat focused — only what’s relevant to that question, not your entire case file in one running conversation.
- Notice a chat getting “tired” (answers become vaguer, or the assistant refers to something you don’t recognise)? Start again in a fresh chat. You lose nothing: your documents and your dossier stay put.
The product warns you itself
Section titled “The product warns you itself”You do not have to judge this by feel alone: the chat tells you when a conversation is getting too full.
Warnings that escalate. As a conversation grows, the message changes with it:
- “This conversation is getting long”: in long conversations, the quality of answers can gradually decline.
- “This conversation is very long”: we recommend starting a new conversation.
- “This conversation is extremely long”: answer quality is likely to decline noticeably, and we strongly recommend starting over.
- “This conversation is nearing its limit”: older messages will soon be summarised automatically and detail may be lost.
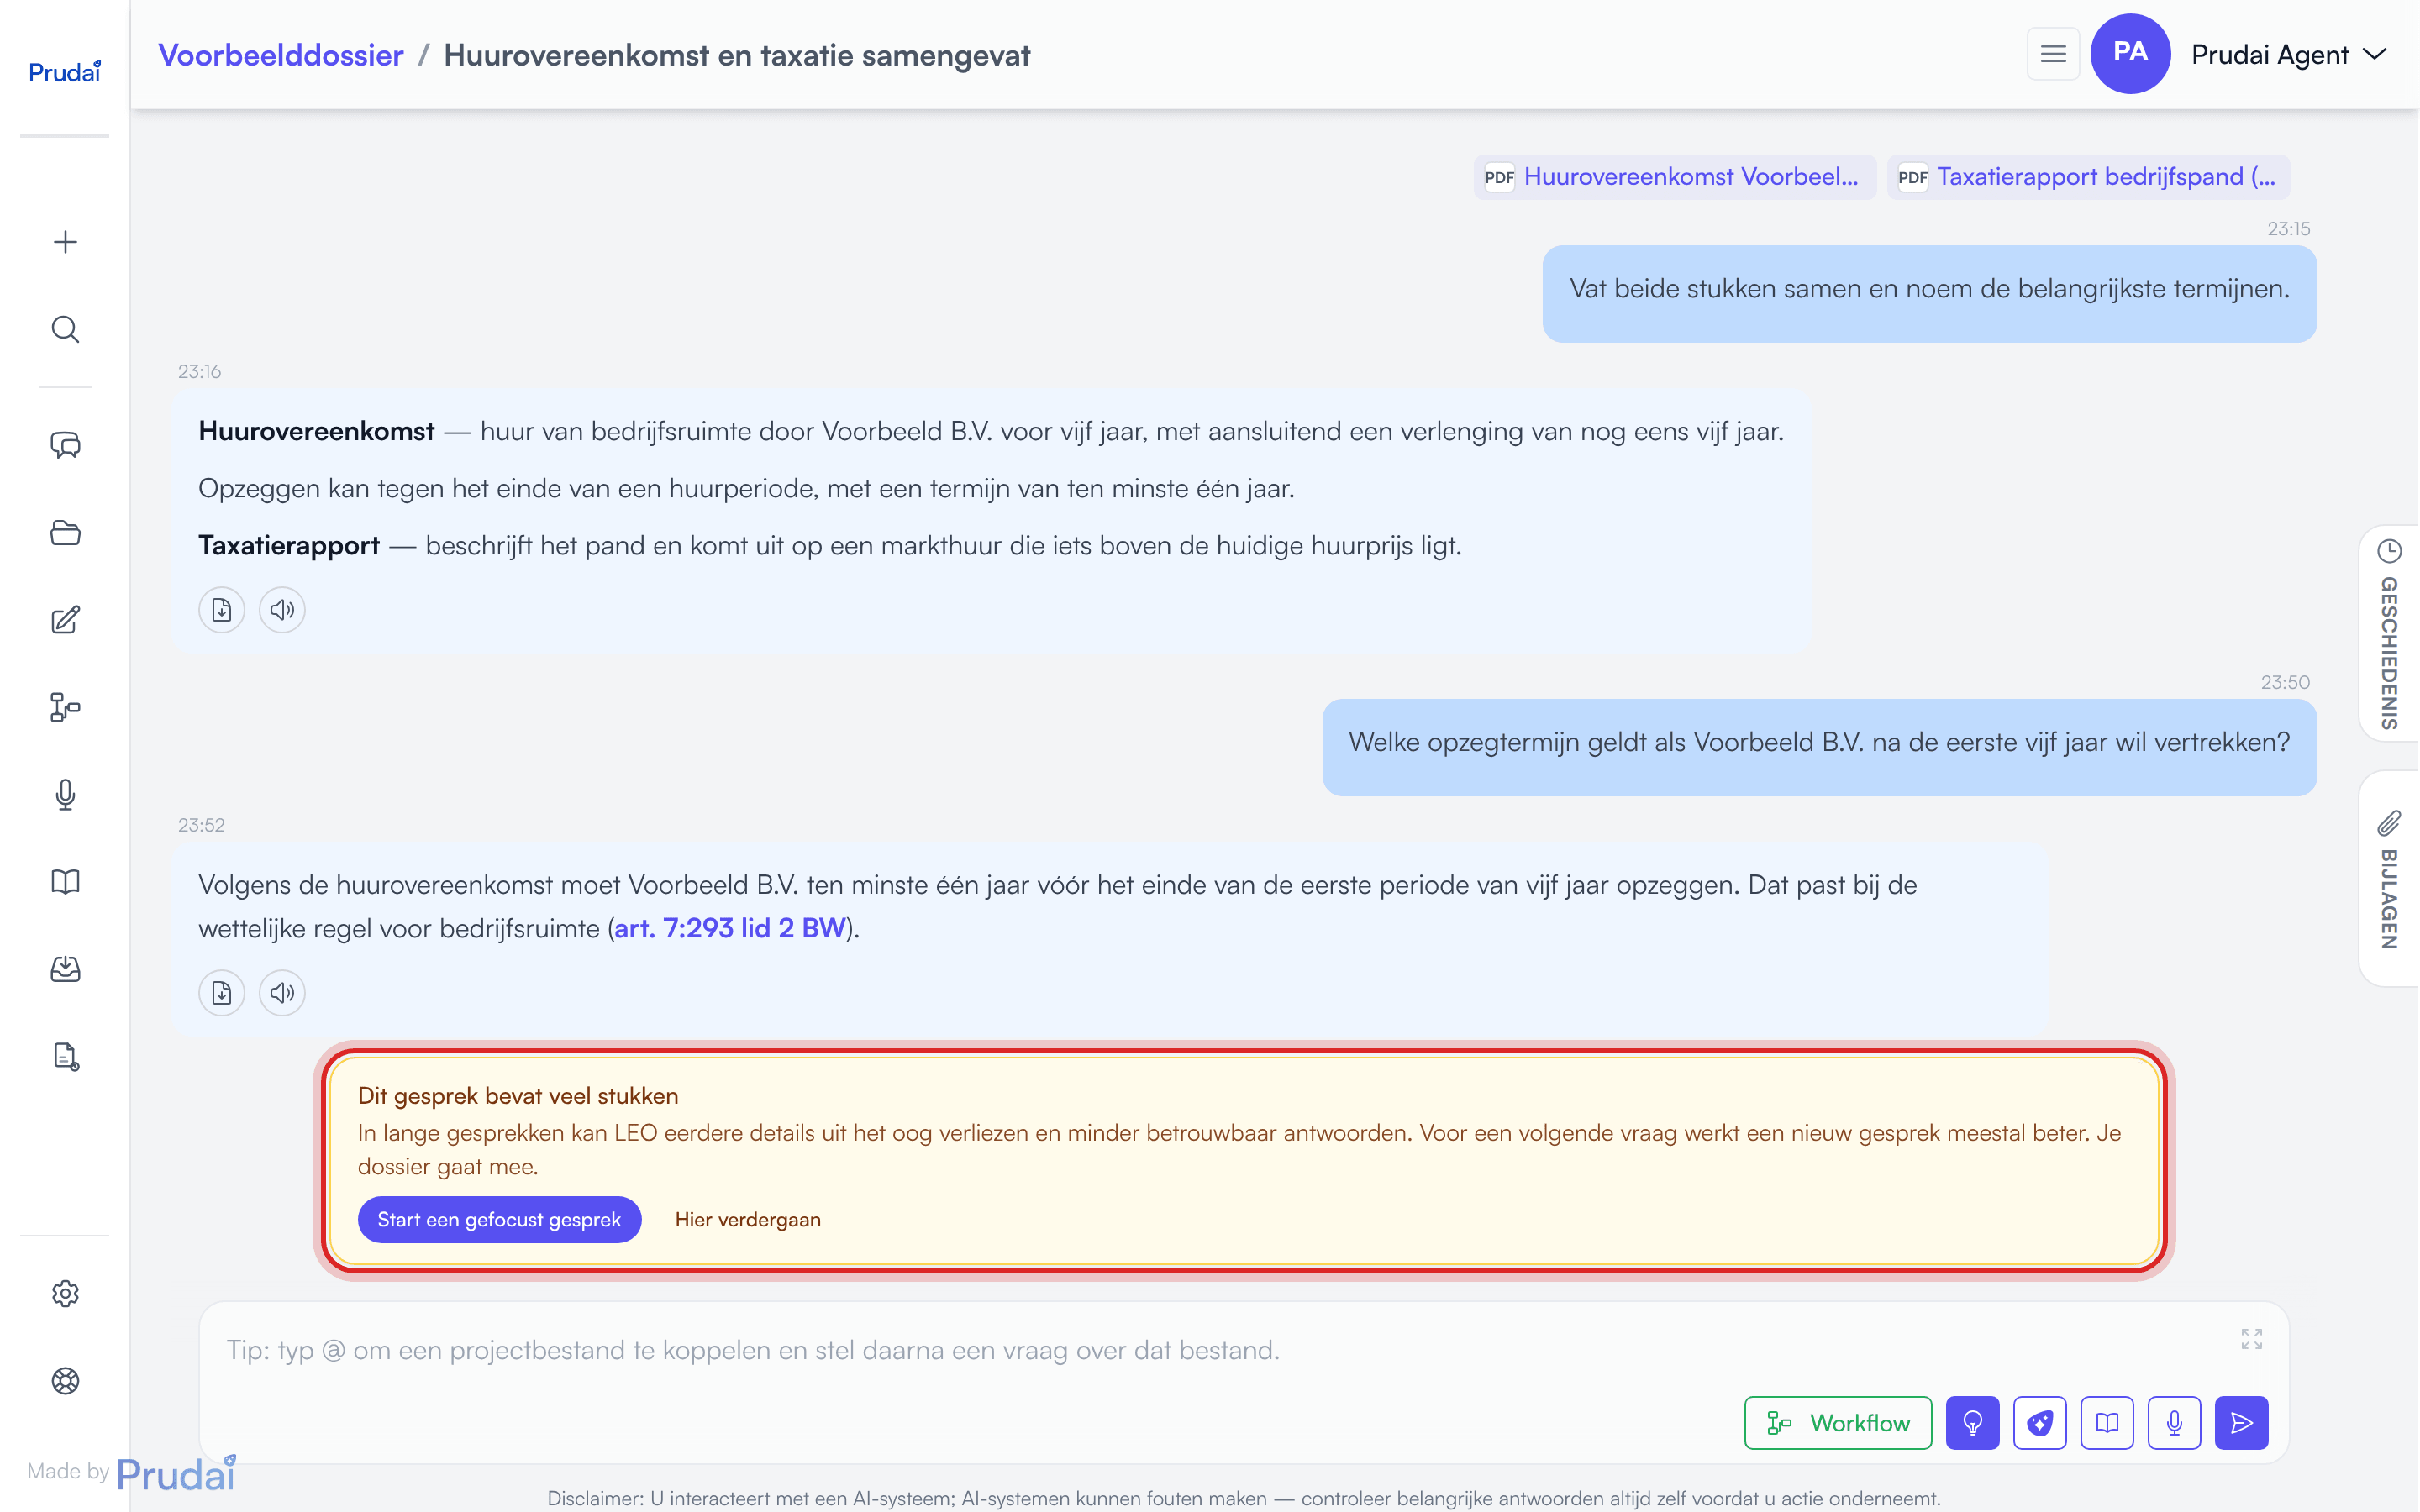
A standing notice in the chat. Alongside those passing warnings, a card can stay in the conversation, also after you reload the page. It has two buttons: Start a focused conversation and Continue here. If the conversation belongs to a dossier, that dossier comes along to the new conversation.
The card’s heading tells you what is going on:
- “This conversation is getting long”: the conversation has many messages.
- “This conversation holds a lot of material”: the length sits in long text in the conversation itself, such as text you paste and long answers from the assistant, even when there are still few messages. Documents you attach and sources the assistant looked up in earlier turns do not count.
- “This conversation is nearing its limit”: the assistant will soon summarise older messages.
Summarising. If you do not act, at some point the assistant summarises older messages itself. You then see the message “Conversation summarised”. The answer still reflects the full conversation, but detail from those older messages can be lost. That is exactly the moment you would rather have got ahead of.
So do not treat these warnings as noise. They are the signal to carry the topic you are working on into a fresh chat.
Always check the source
Section titled “Always check the source”Treat every answer as a draft. Click the source pill or document citation inside the answer and read the source text yourself before you use anything in your advice or court document. See a reference to a document or passage you don’t recognise? Don’t trust it, start a new chat and ask again with only the relevant document attached. More on this: Citations & source availability (login required) and Chat.
This is not just our advice either: below the input field there is a fixed disclaimer stating that you are working with an AI system and should always verify important answers yourself. See Chat.
What the assistant should do
Section titled “What the assistant should do”If the assistant hasn’t actually retrieved a document, it should say so — not guess at its contents. If you notice it quoting a passage that’s wrong anyway, give the message a 👎 (Could be better) with a short note under “What went wrong?”. That signal reaches us and helps us sharpen the assistant further.
Warning for a ruling that was not retrieved
Section titled “Warning for a ruling that was not retrieved”For rulings with an ECLI number, the platform checks this itself. If the assistant mentions an ECLI that was not retrieved in the conversation, it first tries to retrieve that ruling after all. If that fails, a warning appears below the answer:
⚠️ Unverified case-law reference: ECLI number — this ruling was not retrieved from rechtspraak.nl in this conversation and no source confirms it. Check before relying on it.
With the interface set to Dutch, the warning reads Ongeverifieerde bronvermelding. When several rulings are involved, the heading is plural and lists them all.
An ECLI counts as confirmed when it appears in a source the assistant retrieved in this conversation, in a document you added, or in your own message. An earlier answer from the assistant does not count: having mentioned the number before proves nothing. When you see the warning, look the ruling up yourself before you use it.
Having a document reviewed
Section titled “Having a document reviewed”When you ask LEO to read a document critically (“review this memo”, “give me a second opinion”), it follows a fixed structure. That structure belongs to LEO; LEO Fiscaal does not follow it.
- First the type of document and the reader. At the top, one sentence states which type of document and which reader LEO assumed, for example a court filing for the judge or a note for a board. If that is wrong, say so: LEO judges the document by the standard of that type.
- Three to five findings at most: the points that matter most for that reader. Each finding ends with a proposal for how to rephrase the passage.
- Every finding starts with a label. In the chat it appears as a coloured label with an icon in front of the finding. LEO writes these labels in Dutch:
- Fout (error): a source retrieved in this conversation directly contradicts the statement, and LEO found nothing pointing the other way. LEO quotes that source verbatim.
- Aandachtspunt (point of attention): professionals can disagree on it, it depends on the facts, or sources point both ways. LEO gives both readings.
- Suggestie (suggestion): an optional improvement, not a flaw.
- A cautious statement is never an error. If the author writes “seems”, “possibly” or “in my estimate”, LEO judges how strong the argument is, not whether it is “correct”.
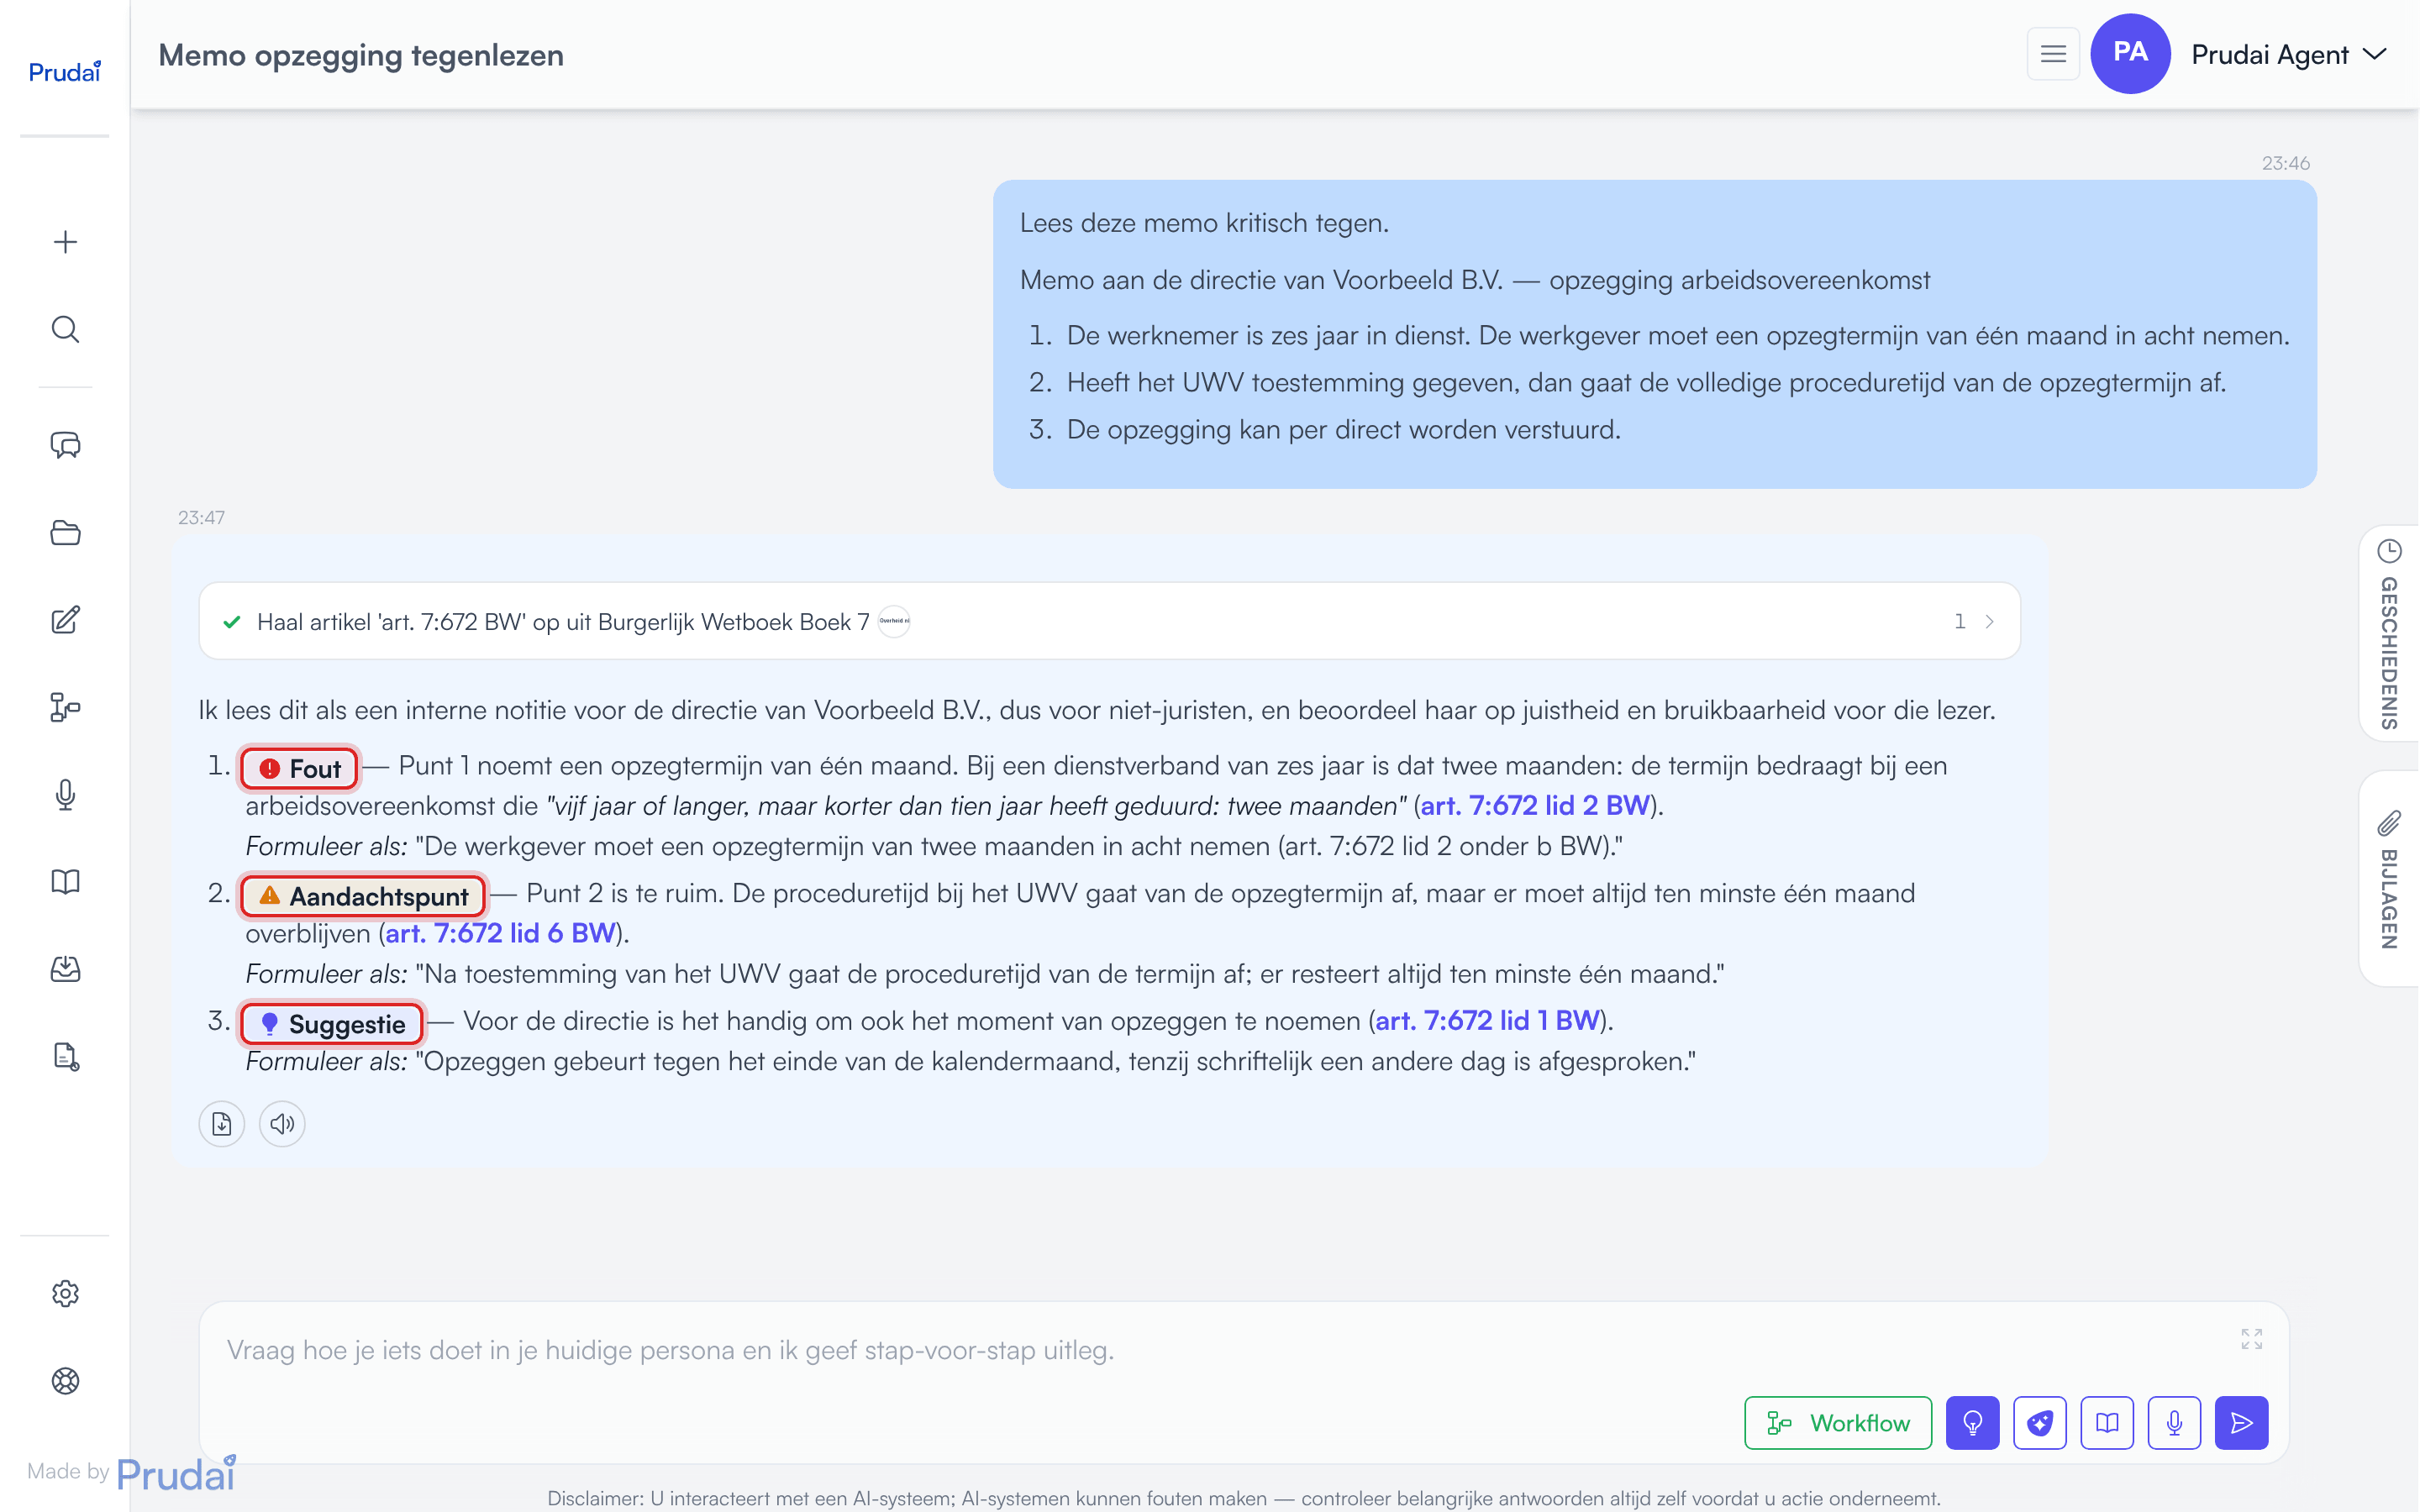
If you copy or export the answer, it simply shows the word, for example “Fout — …”.
When an answer is slow or stalls
Section titled “When an answer is slow or stalls”A thorough answer can take a while. If it takes longer than usual, you see “Still working — this answer is taking a bit longer.” When the thinking depth is set to Thorough or Ultra, you also get the tip to pick a lower setting. When the assistant writes a long piece, such as a document of thousands of words, you see a step in progress in the sources bar, and the answer does not stall halfway.
If nothing comes in for too long, the chat stops with one of these messages:
- “The response took too long to start. Please try again.”
- “The response stalled. Please try again.”
Then ask your question again. If it keeps happening with a large task, pick a lower thinking depth or split the task into parts. If it keeps going wrong, let us know via Support.
If you reload the page while the assistant is still working, you see “Your previous question is still being answered”: the answer is finished and appears as soon as it is ready.
What the research shows
Section titled “What the research shows”This isn’t a Prudai quirk but a well-documented property of every current AI model:
- Long inputs become less reliable. Independent research tested 18 leading models from different providers and found performance degrades steadily as the input grows — even on simple tasks.
- Information in the “middle” is used less well. Models use information at the beginning and end of a long context better than information buried in the middle.
- Long conversations amplify this. Across multiple turns, accuracy drops by roughly 39% on average versus a single focused question. A key cause: when a model is missing something, it sometimes “fills in” an assumption and then anchors on it — exactly the pattern you want to avoid.
This is precisely why “a new chat per topic” works: you keep the context short, so the model never falls into that pattern.
Further reading
Section titled “Further reading”- Kelly Hong, Anton Troynikov, Jeff Huber — Context Rot: How Increasing Input Tokens Impacts LLM Performance (Chroma, 2025).
- Nelson F. Liu et al. — Lost in the Middle: How Language Models Use Long Contexts (TACL, 2024).
- Philippe Laban, Hiroaki Hayashi, Yingbo Zhou, Jennifer Neville — LLMs Get Lost in Multi-Turn Conversation (2025).
- Lei Huang et al. — A Survey on Hallucination in Large Language Models (2023).